RAG and embeddings: making AI answer from your documents
How "meaning-based" search works, what embeddings and vector databases are, how to build an assistant that answers from company documents citing sources, and the mistakes that make it unreliable.
 Mattia PanattaUpdated 13 October 202613 minAdvanced
In short
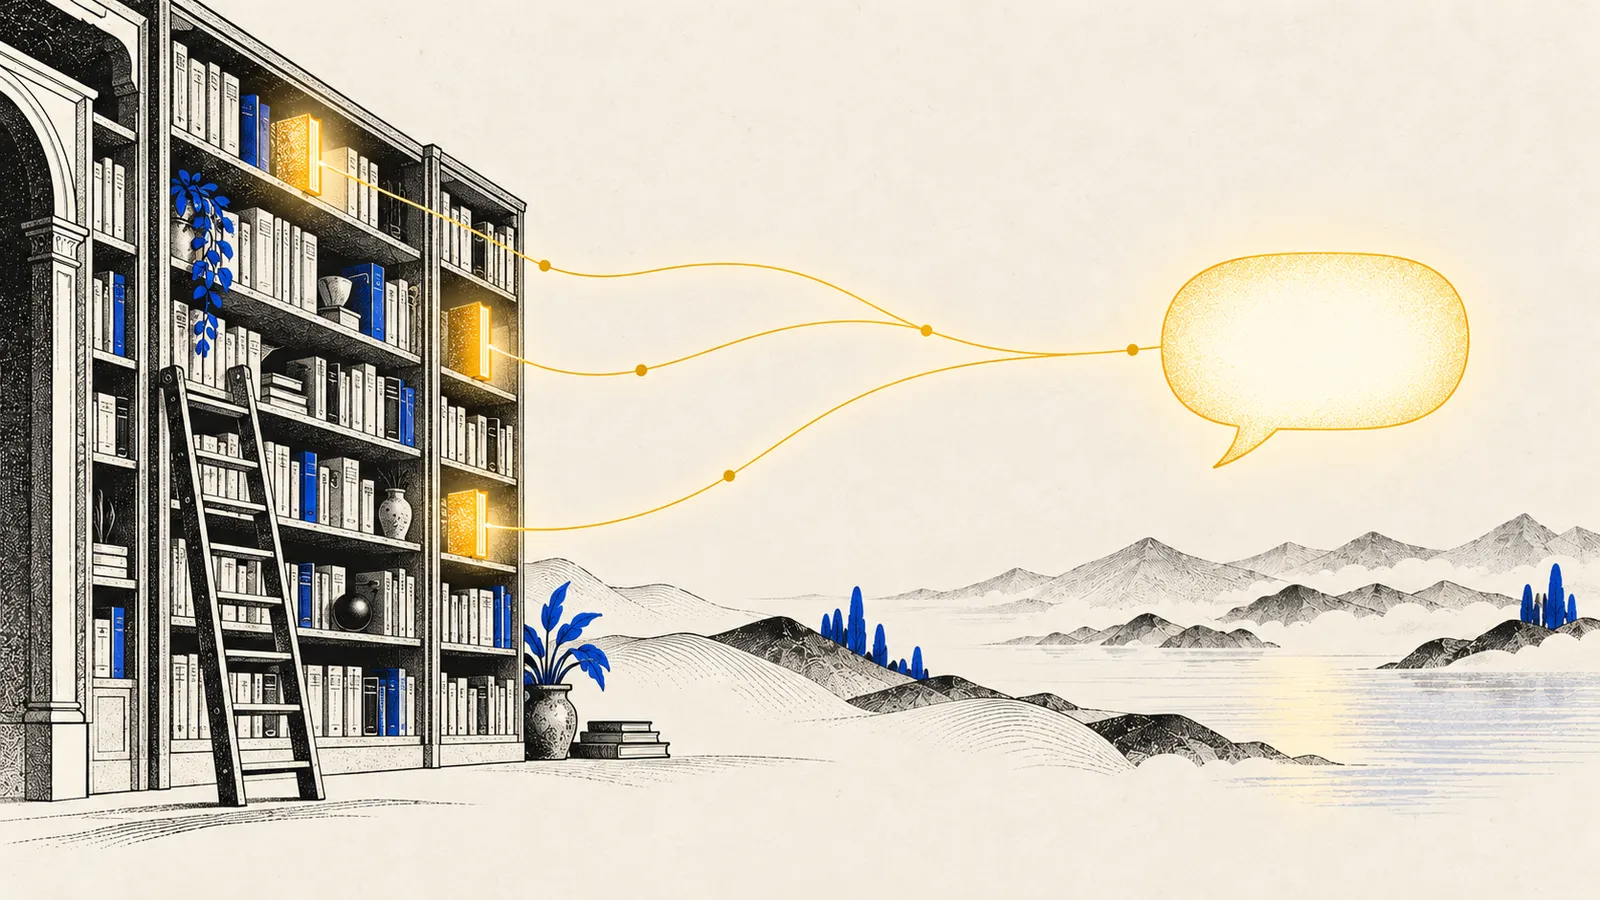
- RAG (Retrieval-Augmented Generation) means: first search for the right passages in your documents, then have the model answer only from those.
- “Meaning-based” search uses embeddings: each text becomes a point in a space where similar texts sit close together.
- Quality depends mostly on how you split and prepare documents, not on the model.
- A good RAG system cites sources and can say “I didn’t find it”. If it doesn’t, it isn’t reliable.
The problem it solves
A model like GPT-6.1 Sol knows a lot about the world but nothing about you: the internal manual, supplier contracts, the firm’s procedures, five years of client memos. And even if it did, its knowledge stops at its training date.
Could you paste everything into the context, now that windows reach a million tokens? For a few documents, yes. With thousands of pages it’s too costly and slow and, as we saw in the context and memory guide, information in the middle gets less weight. The solution is giving the model only the passages it needs, every time.
How it works, step by step
1. Prepare the documents
Documents are converted to text (scanned PDFs too, via OCR) and split into chunks of a few hundred words, ideally following the structure: a contract clause, a manual section, an FAQ entry.
2. Compute embeddings
A dedicated model turns each chunk into an embedding: a list of hundreds or thousands of numbers representing its meaning. Texts about the same thing, even in different words (“early termination” and “cancellation before expiry”), end up close together.
3. Store in an index
Embeddings go into a vector database (or a regular database with vector functions) that finds the nearest points to another point in milliseconds.
4. Search
When a question arrives, it too becomes an embedding. The system takes the nearest chunks, often combining meaning-based search with classic keyword search: the former understands synonyms, the latter doesn’t miss acronyms, codes and clause numbers (hybrid search). A reranking step can then reorder results by relevance.
5. Answer with citations
The retrieved chunks go into the context with the question and precise instructions: answer only from these texts, cite where each claim comes from, say so if you can’t find the answer.
See it in action on this site
Lumen’s chatbot works this way: site pages are split into sections and indexed; when you ask, the model calls a search tool, reads the passages found and answers with links to the exact sections. For fresh news it runs a second search, on the web, restricted to four reliable sites.
Mistakes that make RAG unreliable
- Badly cut chunks. If a contract clause is split in half, the answer loses the exception in the second half. Cut along the structure and leave a small overlap between chunks.
- Old and new documents mixed. Three versions of the same procedure in the index produce contradictory answers. Clean up before indexing and mark dates and versions.
- Semantic search only. Embeddings struggle with codes, acronyms and numbers (“art. 2426”, “form F24”). Hybrid search solves most of it.
- No “I don’t know”. If the system always answers, it will answer even when it found nothing, inventing. Instructions must allow “not in the documents”.
- No evaluation. Prepare 30-50 real questions with the right answer and measure how often the system finds the correct document. It’s the only way to know whether changes help or hurt.
- Permissions ignored. A company assistant must not show HR documents to everyone. Access control must be applied before the search.
Build or buy?
| Need | Solution |
|---|---|
| Studying or working on a few documents, alone | Gemini Notebook, ChatGPT and Claude Projects |
| Team assistant, documents in Drive/SharePoint | Enterprise search features in Business/Enterprise plans, MCP connectors |
| Website chatbot or very specific documents | Custom system (n8n with vector nodes, open-source libraries, or a developer) |
| Data that can’t leave the company | RAG with model and index on your own servers |
The prompt that makes the difference
Even with the best search engine, the final answer depends on the instructions. These are the essentials, to adapt.
Answer the question using ONLY the documents provided below. For every claim, give in brackets the document and section it comes from. If the documents don’t contain the answer, write: “I couldn’t find this information in the available documents” and suggest whom to ask. If two documents contradict each other, flag it with their dates. Don’t use outside knowledge, don’t make assumptions.
DOCUMENTS: [passages found by the search]
QUESTION: [user question]
“Agentic” RAG: the next step
Newer systems don’t search just once: the agent decides what to search, reads, notices something is missing, searches again with different words, compares sources and only then answers. Slower and costlier, but far more reliable on complex questions. It’s also how assistants’ Deep Research modes work (see the agents, MCP and Skills guide).
In practice
- For personal use, use ready-made tools: loading documents into a notebook or project is RAG without code.
- For a company, the real work is on the documents: cleanup, versions, structure, permissions.
- Always demand citations and the ability to say “I don’t know”.
- Measure with a set of real questions before and after every change.
Sources
- Lewis et al., "Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks" (2020)
- IBM Technology — What is Retrieval-Augmented Generation (RAG)?
- IBM Technology — RAG's Evolution, from Simple Retrieval to Agentic AI
- IBM Technology — What is a Vector Database?
- IBM Technology — What are Word Embeddings?
Informational content, current as of the date shown. Prices, models and rules change often: always check official sources. Written with the support of AI tools and reviewed by the author.